Back up what you already have
Protect supported Windows and Linux systems through Central while keeping your current hosting or hardware. Agree what gets backed up and where you would restore it if the original system failed.
See backup management →Keep your existing servers, move to a cloud VM or plan a way to roll back and recover. Central’s backup tools and RuntimeOS recovery environment give you options. We help you choose a route, protect the right data and plan how to get working again.
You can combine these options. The right plan depends on what you run, where you want it to run and how quickly you need it back.
Protect supported Windows and Linux systems through Central while keeping your current hosting or hardware. Agree what gets backed up and where you would restore it if the original system failed.
See backup management →If you want to move away from your current server, we can plan a migration to a DC Core cloud VM. Check application compatibility, size the VM and agree backup, testing and cutover steps before making the move.
Explore managed cloud hosting →For supported setups, plan to return a disk partition to an earlier recovery point after a failed update or unwanted change. Keep separate backup copies too, so a failed disk or lost site does not take away your recovery route.
Plan your recovery points →RuntimeOS is our lightweight Linux version of the runtime, for recovery or stateless compute. Include it in the plan when you need a recovery environment separate from the operating system you are restoring.
See where RuntimeOS fits →A move to the cloud changes where your system runs. Rollback returns it to an earlier state. Backups protect recovery copies, and RuntimeOS provides an environment for recovery. We check which combination your systems support.
Before an incident, we agree how to start RuntimeOS on supported hardware, which recovery copies to use and where the restored system will run. A typical recovery plan follows these steps:
RuntimeOS also supports stateless compute: workloads designed so the compute environment can be replaced, with persistent data kept separately. That data still needs its own backup and recovery plan.
Back up supported Windows and Linux systems through the Central agent. It checks what preparation is needed, including whether to take a snapshot. Use Backup Manager to view your backups and choose a recovery point.
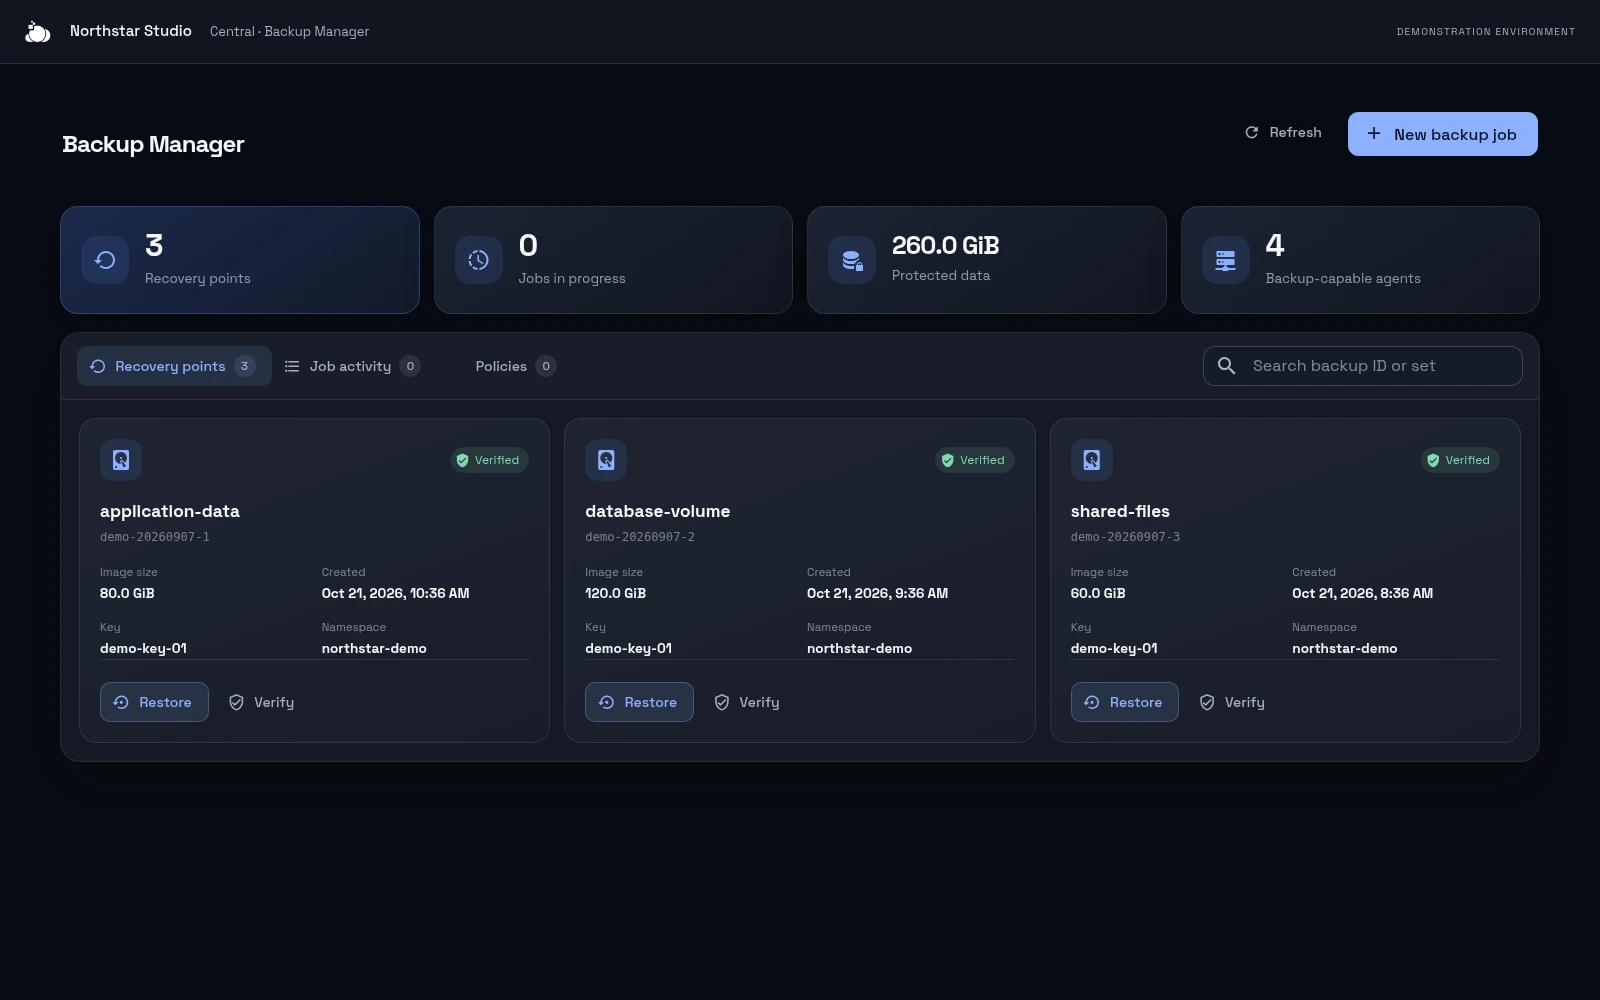
Backup tools are included in your Central subscription. Backup usage is charged separately, and you can add managed backup checks and recovery help.
Our relay system connects Central to your systems, with alternative relay capacity where the setup supports it. Relays provide the connection; backups and recovery capacity provide the way back.
For DC Core-managed services, our standard UK/France setup uses London as the primary location and France for disaster recovery capacity. Recovery in another zone depends on the copies, capacity and steps arranged for your service. Relay traffic and backup storage follow different paths; storage locations are agreed for your service.
Explore the relay system · See our resilience and security details
We start with a few practical questions, then agree a plan that fits your business.
| The question | What we plan together |
|---|---|
| What needs protecting? | The servers, files, databases and other services you need to restore. |
| How far back might you need to go? | How often backups run and how long we keep them. Daily backups are standard for platform-managed systems. |
| How much recent work could you lose? | How recent a recovery copy needs to be. This is the recovery point objective (RPO). |
| How long could you be offline? | The target time to get running again, including any standby capacity needed. This is the recovery time objective (RTO). |
| How do we check it works? | Periodic backup and restore checks, with results for your systems where agreed. |
Recovery times depend on what failed and the service you choose. We agree any guaranteed targets and dedicated standby capacity in your contract.
You tell us which systems matter most and which need to come back first. We agree what we protect, who restores it and who checks it is working.
For example, getting an application back may also mean restoring its database, network access and sign-in service. We plan those steps together. Applications and third-party systems need to be included in the plan to be covered; systems hosted elsewhere follow the storage and recovery setup agreed for them.
Tell us what it does, where it runs and how long you could manage without it. We’ll help you choose between backing up in place, moving to a cloud VM, partition rollback and RuntimeOS recovery. Backup usage, cloud resources and managed help are priced separately from your Central subscription.